Paper I — Q5
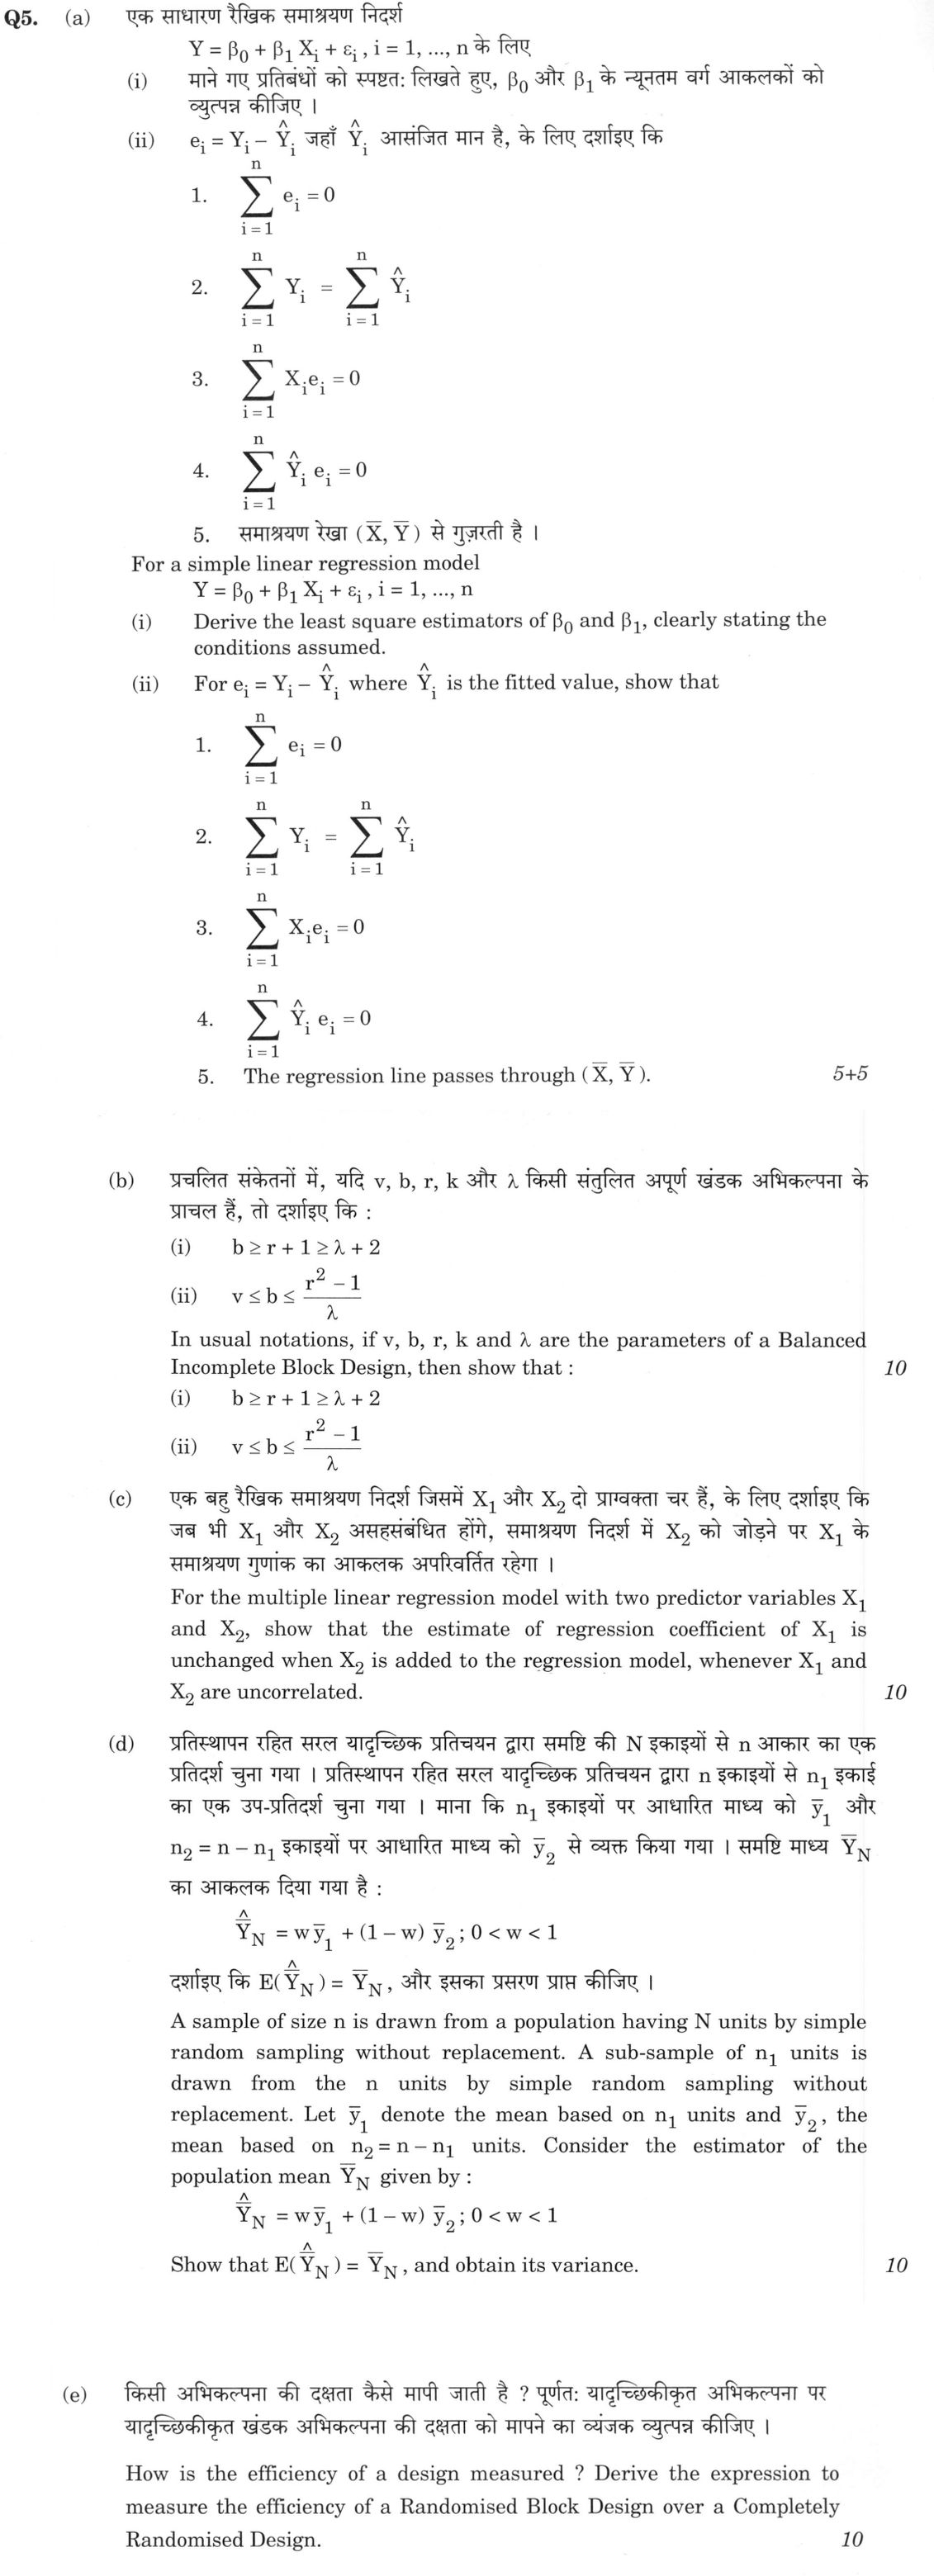
(a) For a simple linear regression model Y = β₀ + β₁Xᵢ + εᵢ, i = 1, ..., n (i) Derive the least square estimators of β₀ and β₁…
For a simple linear regression model Y = β₀ + β₁Xᵢ + εᵢ, i = 1, ..., n
Derive the least square estimators of β₀ and β₁, clearly stating the conditions assumed.
For eᵢ = Yᵢ - Ŷᵢ where Ŷᵢ is the fitted value, show that 1. Σᵢ₌₁ⁿ eᵢ = 0 2. Σᵢ₌₁ⁿ Yᵢ = Σᵢ₌₁ⁿ Ŷᵢ 3. Σᵢ₌₁ⁿ Xᵢeᵢ = 0 4. Σᵢ₌₁ⁿ Ŷᵢeᵢ = 0 5. The regression line passes through (X̄, Ȳ). 5+5
In usual notations, if v, b, r, k and λ are the parameters of a Balanced Incomplete Block Design, then show that : b ≥ r + 1 ≥ λ + 2
v ≤ b ≤ (r² - 1)/λ 10
For the multiple linear regression model with two predictor variables X₁ and X₂, show that the estimate of regression coefficient of X₁ is unchanged when X₂ is added to the regression model, whenever X₁ and X₂ are uncorrelated. 10 marks
A sample of size n is drawn from a population having N units by simple random sampling without replacement. A sub-sample of n₁ units is drawn from the n units by simple random sampling without replacement. Let ȳ₁ denote the mean based on n₁ units and ȳ₂, the mean based on n₂ = n - n₁ units. Consider the estimator of the population mean Ȳₙ given by : Ŷₙ = wȳ₁ + (1-w)ȳ₂ ; 0 < w < 1 Show that E(Ŷₙ) = Ȳₙ, and obtain its variance. 10 marks
How is the efficiency of a design measured ? Derive the expression to measure the efficiency of a Randomised Block Design over a Completely Randomised Design. 10 marks
हिंदी में प्रश्न पढ़ें
एक साधारण रैखिक समाश्रयण निदर्श Y = β₀ + β₁Xᵢ + εᵢ, i = 1, ..., n के लिए
माने गए प्रतिबंधों को स्पष्ट लिखते हुए, β₀ और β₁ के न्यूनतम वर्ग आकलकों को व्युत्पन्न कीजिए।
eᵢ = Yᵢ - Ŷᵢ जहाँ Ŷᵢ आसंजित मान है, के लिए दर्शाइए कि 1. Σᵢ₌₁ⁿ eᵢ = 0 2. Σᵢ₌₁ⁿ Yᵢ = Σᵢ₌₁ⁿ Ŷᵢ 3. Σᵢ₌₁ⁿ Xᵢeᵢ = 0 4. Σᵢ₌₁ⁿ Ŷᵢeᵢ = 0 5. समाश्रयण रेखा (X̄, Ȳ) से गुजरती है। 5+5
प्रचलित संकेतों में, यदि v, b, r, k और λ किसी संतुलित अपूर्ण खंडक अभिकल्पना के प्राचल हैं, तो दर्शाइए कि : b ≥ r + 1 ≥ λ + 2
v ≤ b ≤ (r² - 1)/λ 10
एक बहु रैखिक समाश्रयण निदर्श जिसमें X₁ और X₂ दो प्रावकता चर हैं, के लिए दर्शाइए कि जब भी X₁ और X₂ असहसंबंधित होंगे, समाश्रयण निदर्श में X₂ को जोड़ने पर X₁ के समाश्रयण गुणांक का आकलक अपरिवर्तित रहेगा । 10
प्रतिस्थापन रहित सरल यादृच्छिक प्रतिचयन द्वारा समष्टि की N इकाइयों से n आकार का एक प्रतिदर्श चुना गया । प्रतिस्थापन रहित सरल यादृच्छिक प्रतिचयन द्वारा n इकाइयों से n₁ इकाई का एक उप-प्रतिदर्श चुना गया । माना कि n₁ इकाइयों पर आधारित माध्य को ȳ₁ और n₂ = n - n₁ इकाइयों पर आधारित माध्य को ȳ₂ से व्यक्त किया गया । समष्टि माध्य Ȳₙ का आकलक दिया गया है : Ŷₙ = wȳ₁ + (1-w)ȳ₂ ; 0 < w < 1 दर्शाइए कि E(Ŷₙ) = Ȳₙ, और इसका प्रसरण प्राप्त कीजिए । 10
किसी अभिकल्पना की दक्षता कैसे मापी जाती है ? पूर्णतः यादृच्छिकीकृत अभिकल्पना पर यादृच्छिकीकृत खंडक अभिकल्पना की दक्षता को मापने का व्यंजक व्युत्पन्न कीजिए। 10
The figure this question refers to, in words
The question paper is a scan and the diagram did not survive as text. This is the figure as read from the original page — every component, value and label — so the question can be worked from the text below.
Table: Chi-Square (chi-square) Distribution - Area to the Right of Critical Value. The table lists Degrees of Freedom (1 to 20) in the first column. The subsequent columns represent the area to the right of the critical value with headers: 0.995, 0.99, 0.975, 0.95, 0.90, 0.10, 0.05, 0.025, 0.01, 0.005. The values are as follows: Row 1: -, -, 0.001, 0.004, 0.016, 2.706, 3.841, 5.024, 6.635, 7.879. Row 2: 0.010, 0.020, 0.051, 0.103, 0.211, 4.605, 5.991, 7.378, 9.210, 10.597. Row 3: 0.072, 0.115, 0.216, 0.352, 0.584, 6.251, 7.815, 9.348, 11.345, 12.838. Row 4: 0.207, 0.297, 0.484, 0.711, 1.064, 7.779, 9.488, 11.143, 13.277, 14.860. Row 5: 0.412, 0.554, 0.831, 1.145, 1.610, 9.236, 11.071, 12.833, 15.086, 16.750. Row 6: 0.676, 0.872, 1.237, 1.635, 2.204, 10.645, 12.592, 14.449, 16.812, 18.548. Row 7: 0.989, 1.239, 1.690, 2.167, 2.833, 12.017, 14.067, 16.013, 18.475, 20.278. Row 8: 1.344, 1.646, 2.180, 2.733, 3.490, 13.362, 15.507, 17.535, 20.090, 21.955. Row 9: 1.735, 2.088, 2.700, 3.325, 4.168, 14.684, 16.919, 19.023, 21.666, 23.589. Row 10: 2.156, 2.558, 3.247, 3.940, 4.865, 15.987, 18.307, 20.483, 23.209, 25.188. Row 11: 2.603, 3.053, 3.816, 4.575, 5.578, 17.275, 19.675, 21.920, 24.725, 26.757. Row 12: 3.074, 3.571, 4.404, 5.226, 6.304, 18.549, 21.026, 23.337, 26.217, 28.299. Row 13: 3.565, 4.107, 5.009, 5.892, 7.042, 19.812, 22.362, 24.736, 27.688, 29.819. Row 14: 4.075, 4.660, 5.629, 6.571, 7.790, 21.064, 23.685, 26.119, 29.141, 31.319. Row 15: 4.601, 5.229, 6.262, 7.261, 8.547, 22.307, 24.996, 27.488, 30.578, 32.801. Row 16: 5.142, 5.812, 6.908, 7.962, 9.312, 23.542, 26.296, 28.845, 32.000, 34.267. Row 17: 5.697, 6.408, 7.564, 8.672, 10.085, 24.769, 27.587, 30.191, 33.409, 35.718. Row 18: 6.265, 7.015, 8.231, 9.390, 10.865, 25.989, 28.869, 31.526, 34.805, 37.156. Row 19: 6.844, 7.633, 8.907, 10.117, 11.651, 27.204, 30.144, 32.852, 36.191, 38.582. Row 20: 7.434, 8.260, 9.591, 10.851, 12.443, 28.412, 31.410, 34.170, 37.566, 39.997.
Model answer
Drafted with AI by UPSC Answer Check against this question's marking rubric, to the expected length. UPSC does not publish answers for Mains — this is one way to score well, not an official key. How we build rubrics and answers.
(a)(i) Least squares estimators
Assumptions: the model is linear in β₀, β₁; X is fixed (non-random) with not all Xᵢ equal; E(εᵢ) = 0; Var(εᵢ) = σ²; the εᵢ are uncorrelated. (Normality is needed only for inference, not for least squares.)
Minimise S = Σ(Yᵢ − β₀ − β₁Xᵢ)². Setting ∂S/∂β₀ = 0 and ∂S/∂β₁ = 0 gives the normal equations ΣYᵢ = nβ₀ + β₁ΣXᵢ, ΣXᵢYᵢ = β₀ΣXᵢ + β₁ΣXᵢ². Solving, β̂₁ = Σ(Xᵢ − X̄)(Yᵢ − Ȳ)/Σ(Xᵢ − X̄)², β̂₀ = Ȳ − β̂₁X̄. The second derivatives form a positive-definite matrix when Σ(Xᵢ − X̄)² > 0, so this is a minimum.
(a)(ii) Properties of residuals
The normal equations say Σ(Yᵢ − β̂₀ − β̂₁Xᵢ) = 0 and ΣXᵢ(Yᵢ − β̂₀ − β̂₁Xᵢ) = 0, that is Σeᵢ = 0 and ΣXᵢeᵢ = 0.
- Σeᵢ = 0 (first normal equation).
- Σeᵢ = ΣYᵢ − ΣŶᵢ = 0, so ΣYᵢ = ΣŶᵢ.
- ΣXᵢeᵢ = 0 (second normal equation).
- ΣŶᵢeᵢ = β̂₀Σeᵢ + β̂₁ΣXᵢeᵢ = 0.
- Dividing the first normal equation by n gives Ȳ = β̂₀ + β̂₁X̄, so the line passes through (X̄, Ȳ).
(b) Inequalities for a BIBD
Relations: vr = bk, λ(v − 1) = r(k − 1), with k < v (incomplete design) and Fisher's inequality b ≥ v. (i) Since k < v, λ(v − 1) = r(k − 1) gives r > λ, so r ≥ λ + 1, i.e. r + 1 ≥ λ + 2. Also bk = vr with v > k gives b > r, so b ≥ r + 1. Hence b ≥ r + 1 ≥ λ + 2. (ii) v ≤ b is Fisher's inequality. For the upper bound, put v = 1 + r(k − 1)/λ in b = vr/k: b = r[λ + r(k − 1)]/(λk) = r²/λ − r(r − λ)/(λk). Then (r² − 1)/λ − b = [r(r − λ) − k]/(λk). From b ≥ v we get r ≥ k, and r − λ ≥ 1, so r(r − λ) ≥ r ≥ k. Hence (r² − 1)/λ − b ≥ 0, i.e. b ≤ (r² − 1)/λ. So v ≤ b ≤ (r² − 1)/λ.
(c) Coefficient of X₁ when X₂ is added
Work with deviations from means. For Y on X₁ alone, β̂₁ = S₁y/S₁₁. For Y on X₁ and X₂, the normal equations are S₁₁β̂₁ + S₁₂β̂₂ = S₁y, S₁₂β̂₁ + S₂₂β̂₂ = S₂y. If X₁ and X₂ are uncorrelated, S₁₂ = Σ(X₁ᵢ − X̄₁)(X₂ᵢ − X̄₂) = 0, so the first equation becomes S₁₁β̂₁ = S₁y, giving β̂₁ = S₁y/S₁₁, the same as before. (Likewise β̂₂ = S₂y/S₂₂.) Adding X₂ leaves β̂₁ unchanged; it only reduces the residual sum of squares by β̂₂²S₂₂.
(d) Sub-sampling estimator
Each of ȳ₁ and ȳ₂ is the mean of a simple random sample without replacement from the population (the n₂ units are the rest of the n-unit sample), so E(ȳ₁) = E(ȳ₂) = Ȳ_N. Hence E(Ŷ_N) = wȲ_N + (1 − w)Ȳ_N = Ȳ_N.
With S² the population mean square, Var(ȳ₁) = (1/n₁ − 1/N)S² and Var(ȳ₂) = (1/n₂ − 1/N)S². The overall mean ȳ = (n₁ȳ₁ + n₂ȳ₂)/n has variance (1/n − 1/N)S²; equating this to the expansion of the variance of the combination gives Cov(ȳ₁, ȳ₂) = −S²/N. Therefore Var(Ŷ_N) = S²[w²(1/n₁ − 1/N) + (1 − w)²(1/n₂ − 1/N) − 2w(1 − w)/N] = S²[w²/n₁ + (1 − w)²/n₂ − 1/N]. This is smallest for w = n₁/n, when it equals (1/n − 1/N)S², the variance of the mean of the full sample.
(e) Efficiency of RBD over CRD
The efficiency of one design relative to another with the same number of experimental units is the ratio of the variances of an estimated treatment contrast, which for the same treatment replication is the ratio of their error variances.
For an RBD with t treatments and r blocks, the CRD error variance is estimated from the total mean square after removing treatments, with block and error sums of squares making up the unit-to-unit variation: σ̂²_CRD = [(r − 1)MSB + r(t − 1)MSE]/(rt − 1), where MSB and MSE are the block and error mean squares of the RBD (the within-block sum of squares is taken as r(t − 1)MSE, as treatment effects are small). Hence E(RBD over CRD) = [(r − 1)MSB + r(t − 1)MSE] / [(rt − 1)MSE]. When the error degrees of freedom differ, Fisher's correction multiplies this by (f₁ + 1)(f₂ + 3)/[(f₁ + 3)(f₂ + 1)], where f₁ = (r − 1)(t − 1) and f₂ = t(r − 1). A value above 1 means blocking has reduced the error and the RBD is more efficient.
How this answer will be evaluated
Framework: UPSC Statistics Paper 1
What earns full marks: Rigorous derivations with all steps shown, correct notation, and clear interpretation of results.
Evaluation rubric
Each sub-part is marked on its own, against the marks and word limit printed on the paper.
- (a)(i) (i) Derive the least squares estimators of β₀ and β₁ stating the assumptions, 5 marks 5 marks
derive— given → assumptions → stepwise derivation → result → check
Must cover
- Assumptions: linearity, fixed X not all equal, zero-mean uncorrelated homoscedastic errors
- Normal equations from minimising the sum of squares
- β̂₁ = Sxy/Sxx and β̂₀ = Ȳ − β̂₁X̄
Loses marks
- Omitting the assumptions
- Wrong formula for β̂₀
Earns more
- Second-order condition for a minimum
- Remark that normality is not needed for least squares
Extra mark
- Matrix or deviation form
- (a)(ii) (ii) Show the five residual properties, 5 marks 5 marks
derive— given → assumptions → stepwise derivation → result → check
Must cover
- Σe = 0 and ΣXe = 0 from the normal equations
- ΣY = ΣŶ and ΣŶe = 0 as consequences
- Line passes through (X̄, Ȳ)
Loses marks
- Asserting without reference to the normal equations
Earns more
- Writing ΣŶe = β̂₀Σe + β̂₁ΣXe
Extra mark
- Geometric orthogonality interpretation
- (b) Show b ≥ r + 1 ≥ λ + 2 and v ≤ b ≤ (r² − 1)/λ for a BIBD, 10 marks 10 marks
derive— given → assumptions → stepwise derivation → result → check
Must cover
- Use vr = bk and λ(v − 1) = r(k − 1) with k < v to get r > λ and b > r
- Fisher's inequality b ≥ v
- Upper bound via b = r²/λ − r(r − λ)/(λk) and r(r − λ) ≥ k
Loses marks
- Circular reasoning
- Algebraic errors in the expression for b
Earns more
- Integer step r ≥ λ + 1 and b ≥ r + 1
- Using r ≥ k from b ≥ v
Extra mark
- State when equality holds
- (c) Show that β̂₁ is unchanged when an uncorrelated X₂ is added, 10 marks 10 marks
derive— given → assumptions → stepwise derivation → result → check
Must cover
- Normal equations of the two-predictor model
- S₁₂ = 0 for uncorrelated predictors
- Reduction to β̂₁ = S₁y/S₁₁, same as simple regression
Loses marks
- Ignoring the intercept
- Treating correlated predictors
Earns more
- Working in deviations from means
- Note that only the residual sum of squares changes
Extra mark
- Matrix argument with block-diagonal X'X
- (d) Show E(Ŷ_N) = Ȳ_N and obtain the variance of wȳ₁ + (1 − w)ȳ₂, 10 marks 10 marks
derive— given → assumptions → stepwise derivation → result → check
Must cover
- Each sub-sample mean is unbiased under SRSWOR so the estimator is unbiased
- Var(ȳ₁), Var(ȳ₂) and Cov(ȳ₁, ȳ₂) = −S²/N
- Var = S²[w²/n₁ + (1−w)²/n₂ − 1/N]
Loses marks
- Taking the covariance as zero
- Omitting finite-population correction terms
Earns more
- Justification of the covariance from the variance of the full-sample mean
- Optimal w = n₁/n
Extra mark
- Comparison with the variance of the full-sample mean
- (e) How is the efficiency of a design measured? Derive the efficiency of RBD over CRD, 10 marks 10 marks
derive— given → assumptions → stepwise derivation → result → check
Must cover
- Efficiency as a ratio of error variances for the same replication
- CRD error variance estimate [(r−1)MSB + r(t−1)MSE]/(rt−1)
- E = [(r−1)MSB + r(t−1)MSE]/[(rt−1)MSE]
Loses marks
- Defining efficiency without reference to variances
- Swapping MSB and MSE
Earns more
- Fisher's degrees-of-freedom correction with f₁ and f₂
- Interpretation of E above 1
Extra mark
- Mention of the approximation in the within-block sum of squares
What "Derive" is asking you to do
Reach the stated expression from a starting relation, justifying every step. The destination is printed in the question, so only the route earns marks, and the assumptions you work under are part of that route.
Structure that answers it
Assumptions and notation defined → starting relation or governing equation → each step with its justification → the required expression → limiting case or boundary check
Where marks are lost
Writing the standard result first and fitting three lines to it, which an examiner reads at a glance. Marks also go on assumptions left unstated — lossless medium, small amplitude, errors independent with zero mean — and on symbols used before they are defined, even when the question says usual notations.
Practice this exact question
Write your answer and it is marked point by point against the model answer above — what you covered, what you missed, what you got wrong.
Evaluate my answer →More from Statistics 2021 Paper I
- Q2 (a) Let Y₁, Y₂, Y₃, ... be independent and identical Poisson random variables with parame…
- Q3 (a) Let X and Y be two independent random variables following exponential distribution wi…
- Q4 (a) Let X₁, X₂, ..., Xₙ be a random sample from Poisson distribution with mean λ > 0. Def…
- Q5 (a) For a simple linear regression model Y = β₀ + β₁Xᵢ + εᵢ, i = 1, ..., n (i) Derive the…
- Q6 (a) For a multiple linear regression model with three covariates X₁, X₂ and X₃, let rᵢⱼ d…
- Q7 (a) (i) What is confounding in factorial experiments ? (ii) A 2^6factorial experiment is…
- Q8 (a) (i) In stratified sampling under optimum allocation, how will you proceed to select u…